Kangning Cui
← Research / Efficient & Reliable ML

01 / Evaluation

Make compression results comparable

NeurIPS'26, ED Track, Poster

LowRankArena

Kangning Cui · Co-first author

Key finding Rankings change across models and budgets; lower parameter counts do not always produce faster inference.
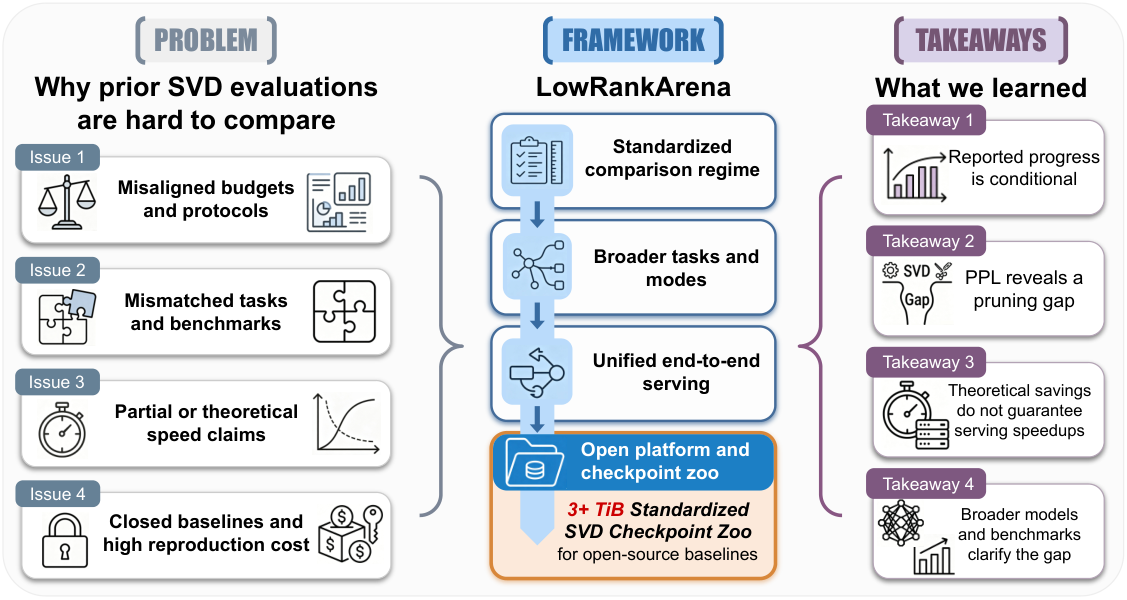
LowRankArena overview: evaluation challenges, a standardized SVD-compression platform, and findings on accuracy and inference efficiencyEnlarge figure
LowRankArena. A shared evaluation pipeline aligns compression budgets, tasks, and serving measurements so that different methods can be compared fairly.
Problem
Different benchmarks and compression budgets make published results hard to compare.
Method
Align task versions, model budgets, and end-to-end inference measurements in one reproducible platform.
Paper Preprint Code PDF (preprint)
BibTeX
@inproceedings{shao2026lowrankarena,
  author = {Shao, Zishan and
            Zhang, Lixun and
            Cui, Kangning and
            Wu, Wenhao and
            Kim, Jinhee and
            Wang, Yixiao and
            Jiang, Ting and
            Ye, Hancheng and
            Wang, Qinsi and
            Yang, Fan and
            Zhuo, Danyang and
            Li, Hai and
            Chen, Yiran},
  title = {{LowRankArena}: A Standardized Evaluation Platform for {SVD}-Based {LLM} Compression},
  booktitle = {The Fortieth Annual Conference on Neural Information Processing Systems},
  year = {2026},
  url = {https://neurips.cc/virtual/2026/poster/139091},
  note = {Accepted conference paper, Evaluations and Datasets Track},
}
Full publication record

02 / Inference

Turn memory savings into useful speed

We examine the execution and decoding choices that determine whether theoretical savings translate into lower serving costs.

Preprint · 2026

FlashSVD

FlashSVD reorganizes the execution of SVD-compressed transformers, with kernels and execution strategies tailored to prefill and autoregressive decoding.

Contribution. Treats the runtime as part of low-rank model design; the preprint evaluates both decode and end-to-end serving performance.

Preprint PDF Code
BibTeX
@misc{wu2026flashsvd,
  author = {Wu, Wenhao and
            Shao, Zishan and
            Cui, Kangning and
            Kim, Jinhee and
            Wang, Yixiao and
            Ye, Hancheng and
            Zhuo, Danyang and
            Chen, Yiran},
  title = {{FlashSVD} v1.5: Making Low-Rank Transformers Inference Actually Fast},
  year = {2026},
  url = {https://arxiv.org/abs/2605.08314v1},
  eprint = {2605.08314},
  archiveprefix = {arXiv},
  version = {1},
  note = {arXiv preprint, version 1},
}
Full publication record

Preprint · 2026

BudgetDraft

BudgetDraft trains a speculative drafter across multiple sparse KV-cache budgets while a verifier retains its full cache. Training aligns sparse views with a shared full-cache target.

Contribution. Addresses the loss of token acceptance as the drafter’s context cache becomes sparse, without adding inference-time components.

Preprint PDF
BibTeX
@misc{he2026budgetdraft,
  author = {He, Liang and
            Wen, Jingbo and
            Zhan, Qishi and
            Chen, Yixiong and
            Cui, Kangning and
            Lan, Qizhen and
            Wang, Xilu},
  title = {{BudgetDraft}: Acceptance-Aware Multi-View Training for Sparse-{KV} Speculative Decoding},
  year = {2026},
  url = {https://arxiv.org/abs/2606.00144v1},
  eprint = {2606.00144},
  archiveprefix = {arXiv},
  version = {1},
  note = {arXiv preprint, version 1},
}
Full publication record

03 / Reliability

Preserve uncertainty after quantization

EMNLP'26, Findings

Doubt-Preserving Quantization

Kangning Cui · Corresponding author

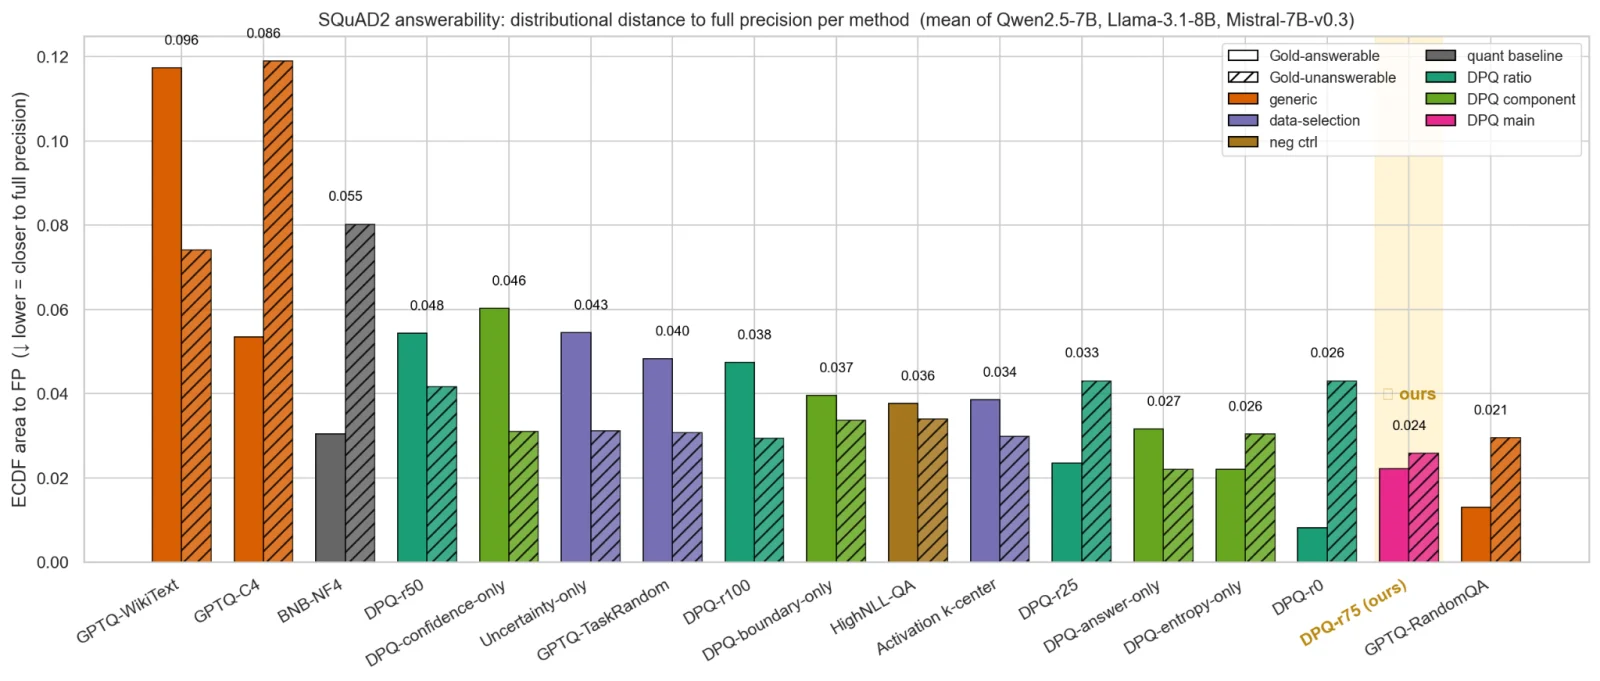
Key finding Answerability and broad QA favor different calibration recipes; the selection adds no inference-time components.

DPQ uncertainty-preservation results for quantized language modelsEnlarge figure
Preserving answerability behavior. Lower bars mean closer agreement with the full-precision model on this SQuAD2 evaluation. The best calibration recipe depends on the behavior being preserved.
Problem
Quantization can keep task accuracy while changing confidence and answerability.
Method
Choose calibration data for the target behavior before applying the quantizer.
Paper Preprint Code PDF
BibTeX
@inproceedings{yang-etal-2026-target,
  author = {Yang, Zhen and
            Hou, Sizai and
            Zheng, Kaiwen and
            Liu, Yaofang and
            He, Liang and
            Chen, Yixuan and
            Cui, Kangning},
  title = {Target-Aware Calibration Data Selection for Preserving Uncertainty in Quantized Language Models},
  booktitle = {Findings of the Association for Computational Linguistics: {EMNLP} 2026},
  editor = {Lee, Hung-Yi and
            Dev, Sunipa and
            Li, Jessy and
            Elliott, Desmond},
  year = {2026},
  pages = {14073--14093},
  publisher = {Association for Computational Linguistics},
  address = {Budapest, Hungary},
  month = {October},
  isbn = {979-8-89176-462-0},
  doi = {10.18653/2026.findings-emnlp.670},
  url = {https://aclanthology.org/2026.findings-emnlp.670/},
}
Full publication record

Research and collaboration

See all publications and preprints in Efficient & Reliable ML, including work on agent behavior and representations. For collaboration, contact Kangning Cui; current recruitment information is on the Team page.