Efficient & Reliable ML
Understanding the cost of compression
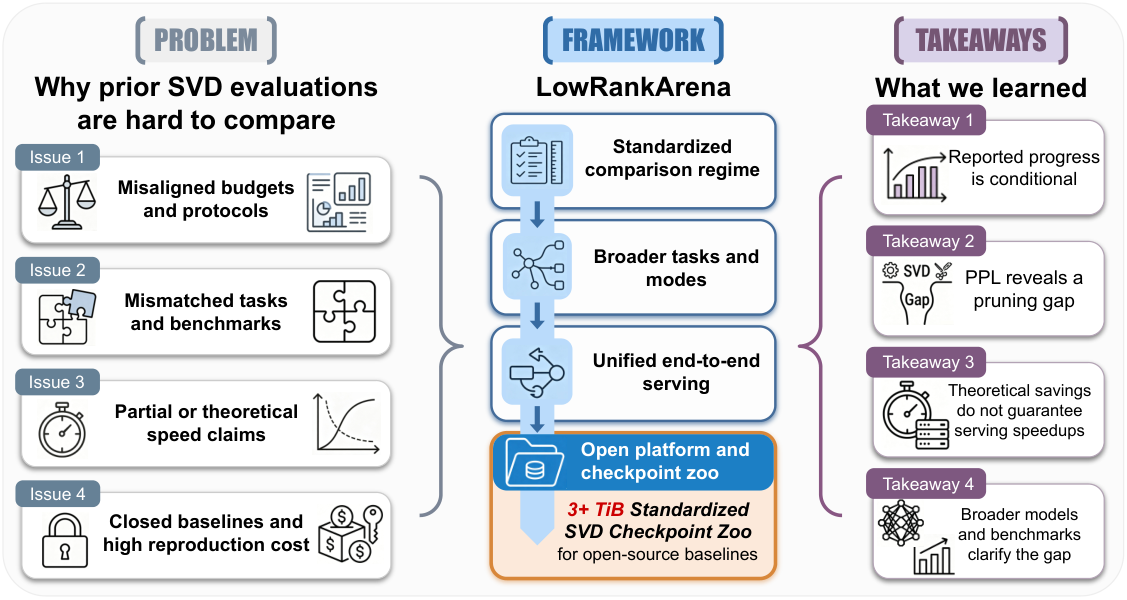
LowRankArena shows that fewer parameters do not always mean faster inference. By exposing trade-offs between model quality, memory, and latency, it helps researchers judge whether compression delivers useful savings under real deployment constraints.
NeurIPS'26, ED Track, Poster
Co-first author